Overview
My research develops visualization methods and open-source software that make exploratory data analysis easier, more flexible, and more reliable. Modern statistical problems increasingly combine multiple data sources and data types, which places greater demands on data preparation, exploration, and visualization before confirmatory analysis. In applied work, I have found that the decisions behind a published analysis are often scattered across the manuscript, supplement, and code, making it difficult to piece them together or to explore how the results would change under alternative decisions. I therefore also study how large language models (LLMs) can help analysts document and extend these decisions, supporting both reproducibility and the exploration of alternatives.
Themes:
Visualization methods and software
Tidy spatio-temporal data and glyph maps
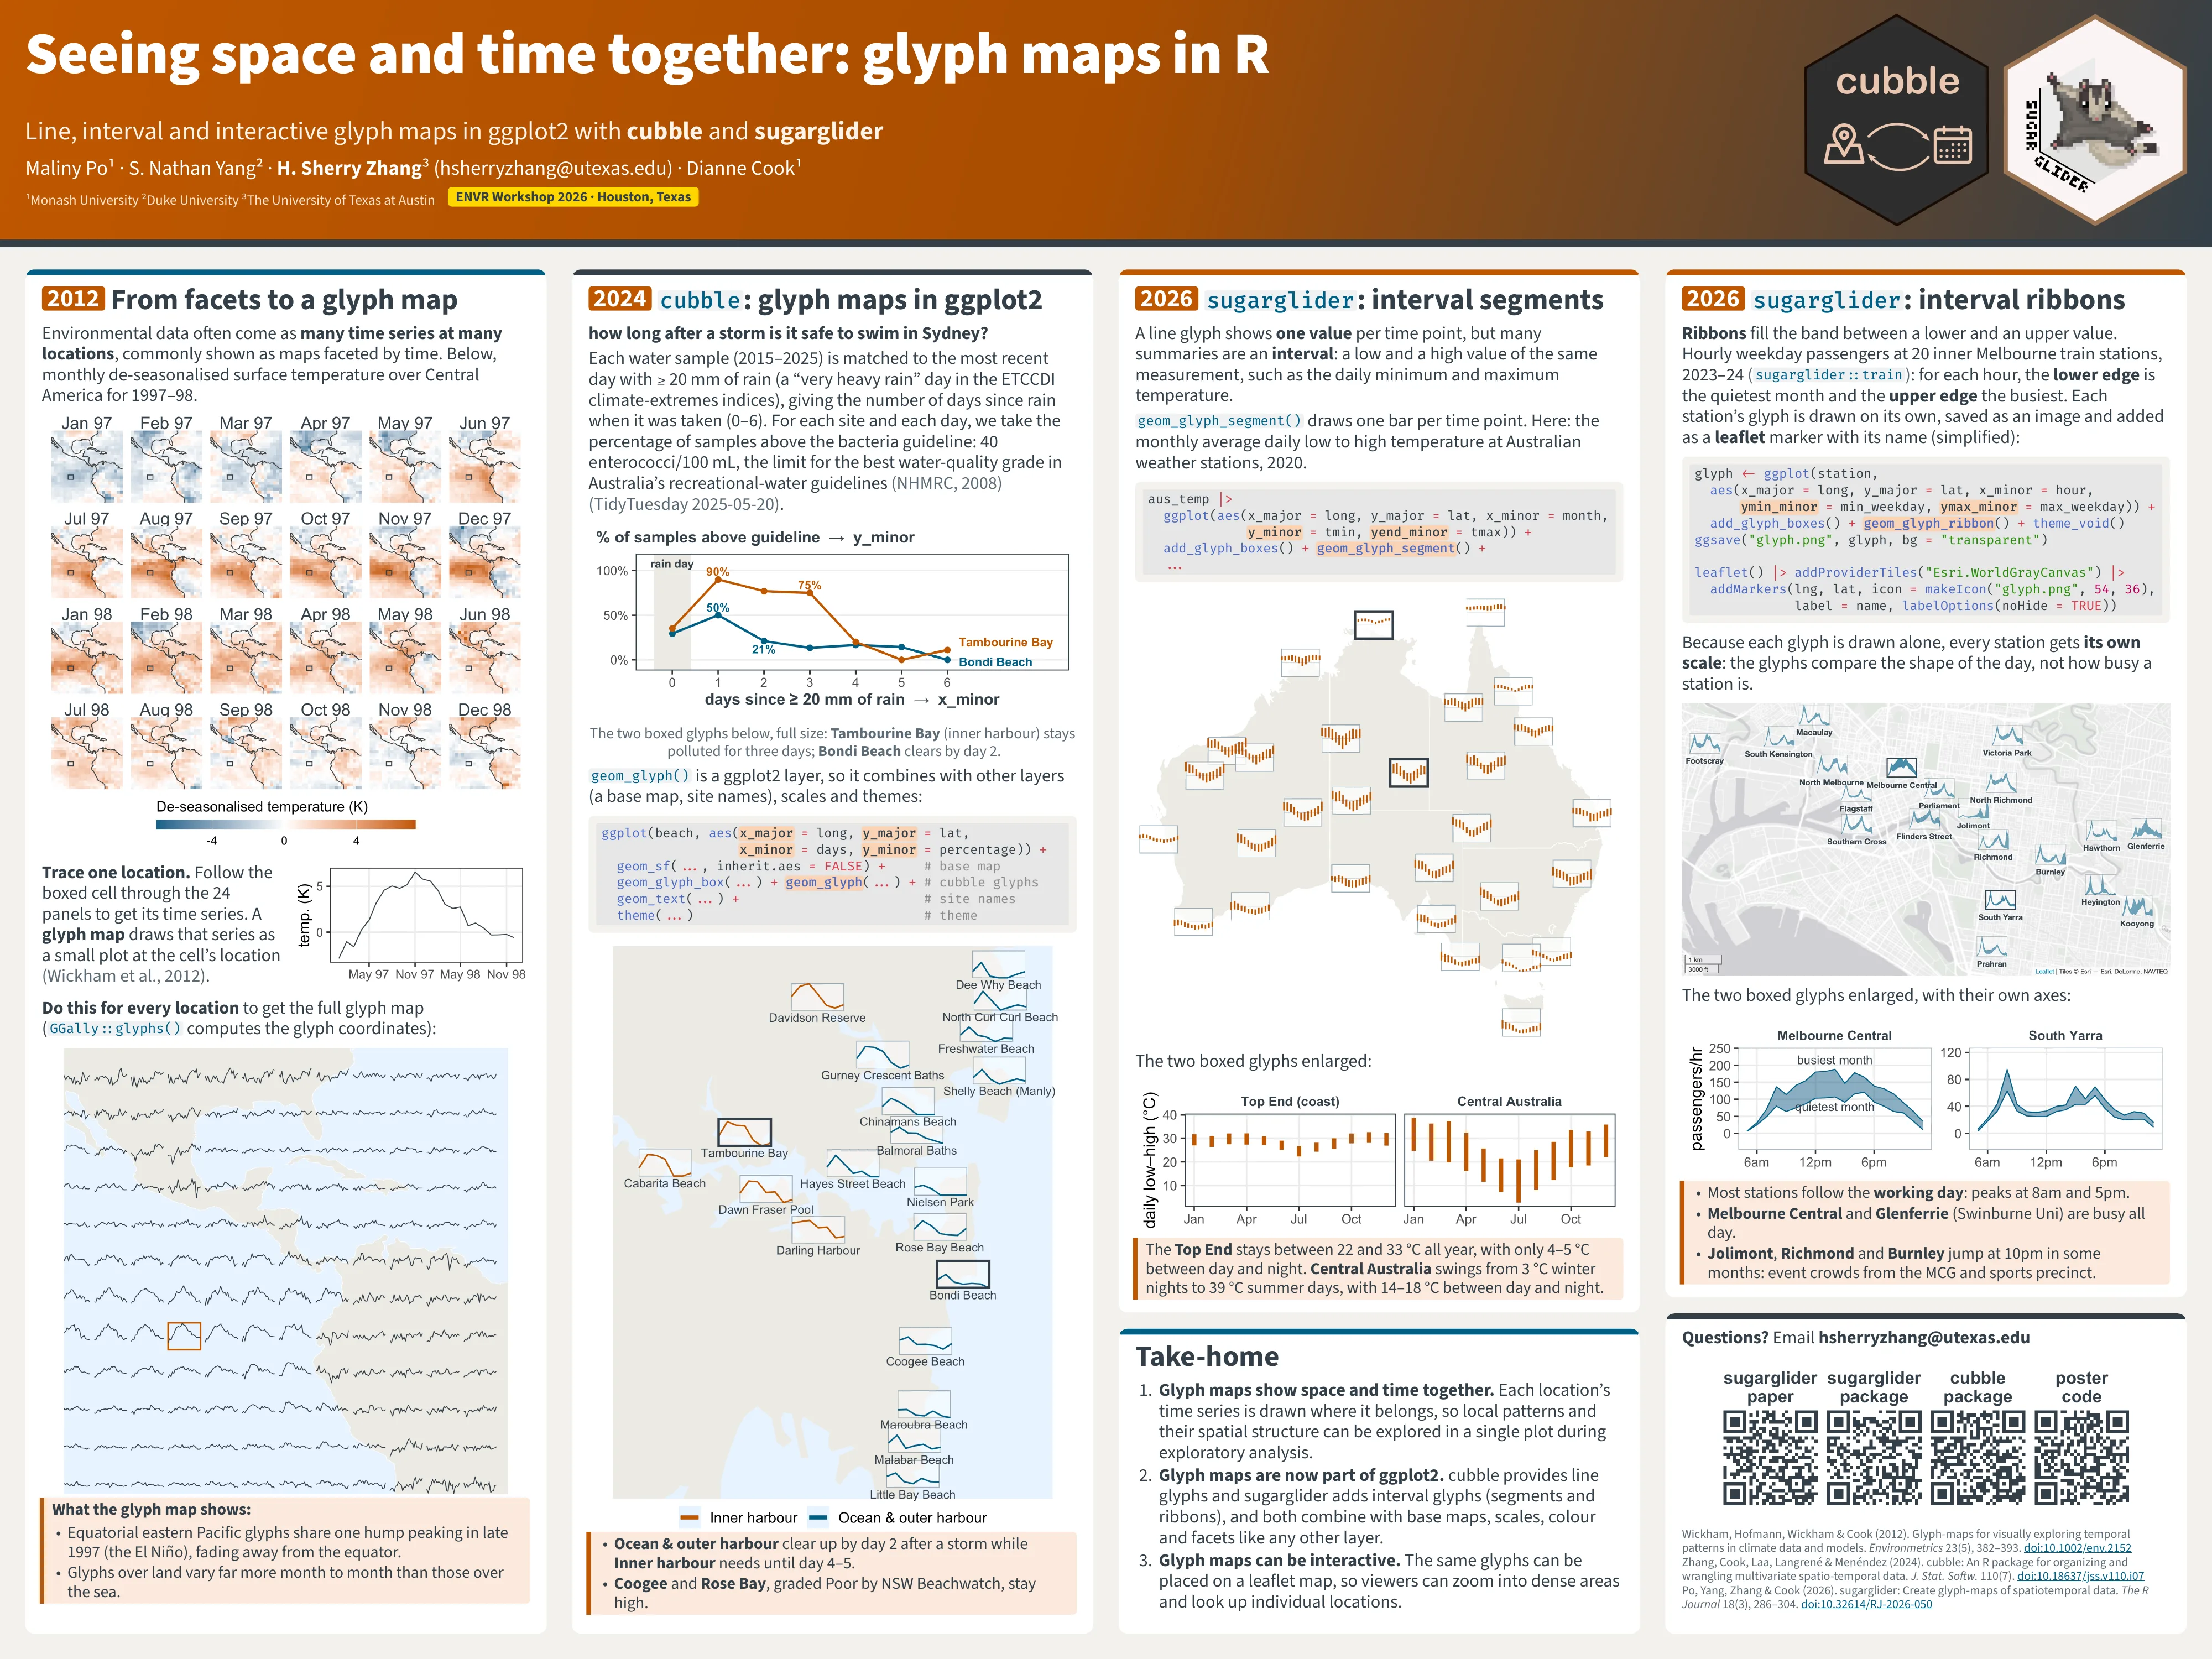
Many environmental and ecological data are collected repeatedly over time at fixed locations, and analyses need to move between the spatial and temporal components or study both at once. Much of the methodological work on such data focuses on modelling, but before and alongside modelling, analysts also need to explore the data: to see how temporal patterns vary across locations, to spot unusual locations or periods, and to check whether the data support a model’s assumptions. The glyph map is one visualization that shows both at once, drawing each location’s time series as a small plot at its geographic position. Figure 1 traces how my work brings glyph maps into the R ecosystem.
Selected work:
- cubble: a tidy data structure for spatio-temporal data that lets analysts switch between spatial and temporal views, with a ggplot2 extension for glyph maps. Journal of Statistical Software, 2024; ASA John M. Chambers Statistical Software Award.
- sugarglider: extends glyph maps beyond line glyphs to ribbon and segment glyphs, developed by the undergraduate and master’s students I supervised in Google Summer of Code 2024. The R Journal, 2026.
- The ggplot2 extension ecosystem: an overview for users and developers, with Joyce Robbins (Columbia University) and Gina Reynolds (University of Denver). Invited submission to WIREs Computational Statistics, minor revision.
Projection pursuit, the guided tour, and interactive graphics
High-dimensional data cannot be seen all at once, but they can be explored through a sequence of low-dimensional projections. A tour animates such a sequence, and projection pursuit guides it towards informative projections by optimizing an index function, which is often non-differentiable and can have local maxima. My work helps understand when this optimization succeeds or fails, by tracing optimizer paths in the projected and original spaces and by characterizing the index functions themselves.
Selected work:
- Visual diagnostics for constrained optimisation with application to guided tours (ferrn). The R Journal, 2021.
- Squintability and other metrics for assessing projection pursuit indexes and guiding optimization choices, which also adds a swarm-based optimizer to the guided tour, with Jessica Leung and collaborators. Journal of Computational and Graphical Statistics, 2026.
- A tidy workflow for index composition (tidyindex): breaks index construction into building blocks, such as dimension reduction or distribution fitting, in the same way that
tidymodelsdoes for modeling, so that analysts can compare indexes, explore design choices, and quantify index uncertainty. Journal of Computational and Graphical Statistics, 2025. - The state-of-the-art on tours for dynamic visualization of high-dimensional data, led by Stuart Lee. WIREs Computational Statistics, 2022.
- Maintainer, with Dianne Cook and Ian Lyttle, of the CRAN Task View: Dynamic Visualizations, a curated guide to R packages for dynamic and interactive graphics.
Transparent data analysis with large language models
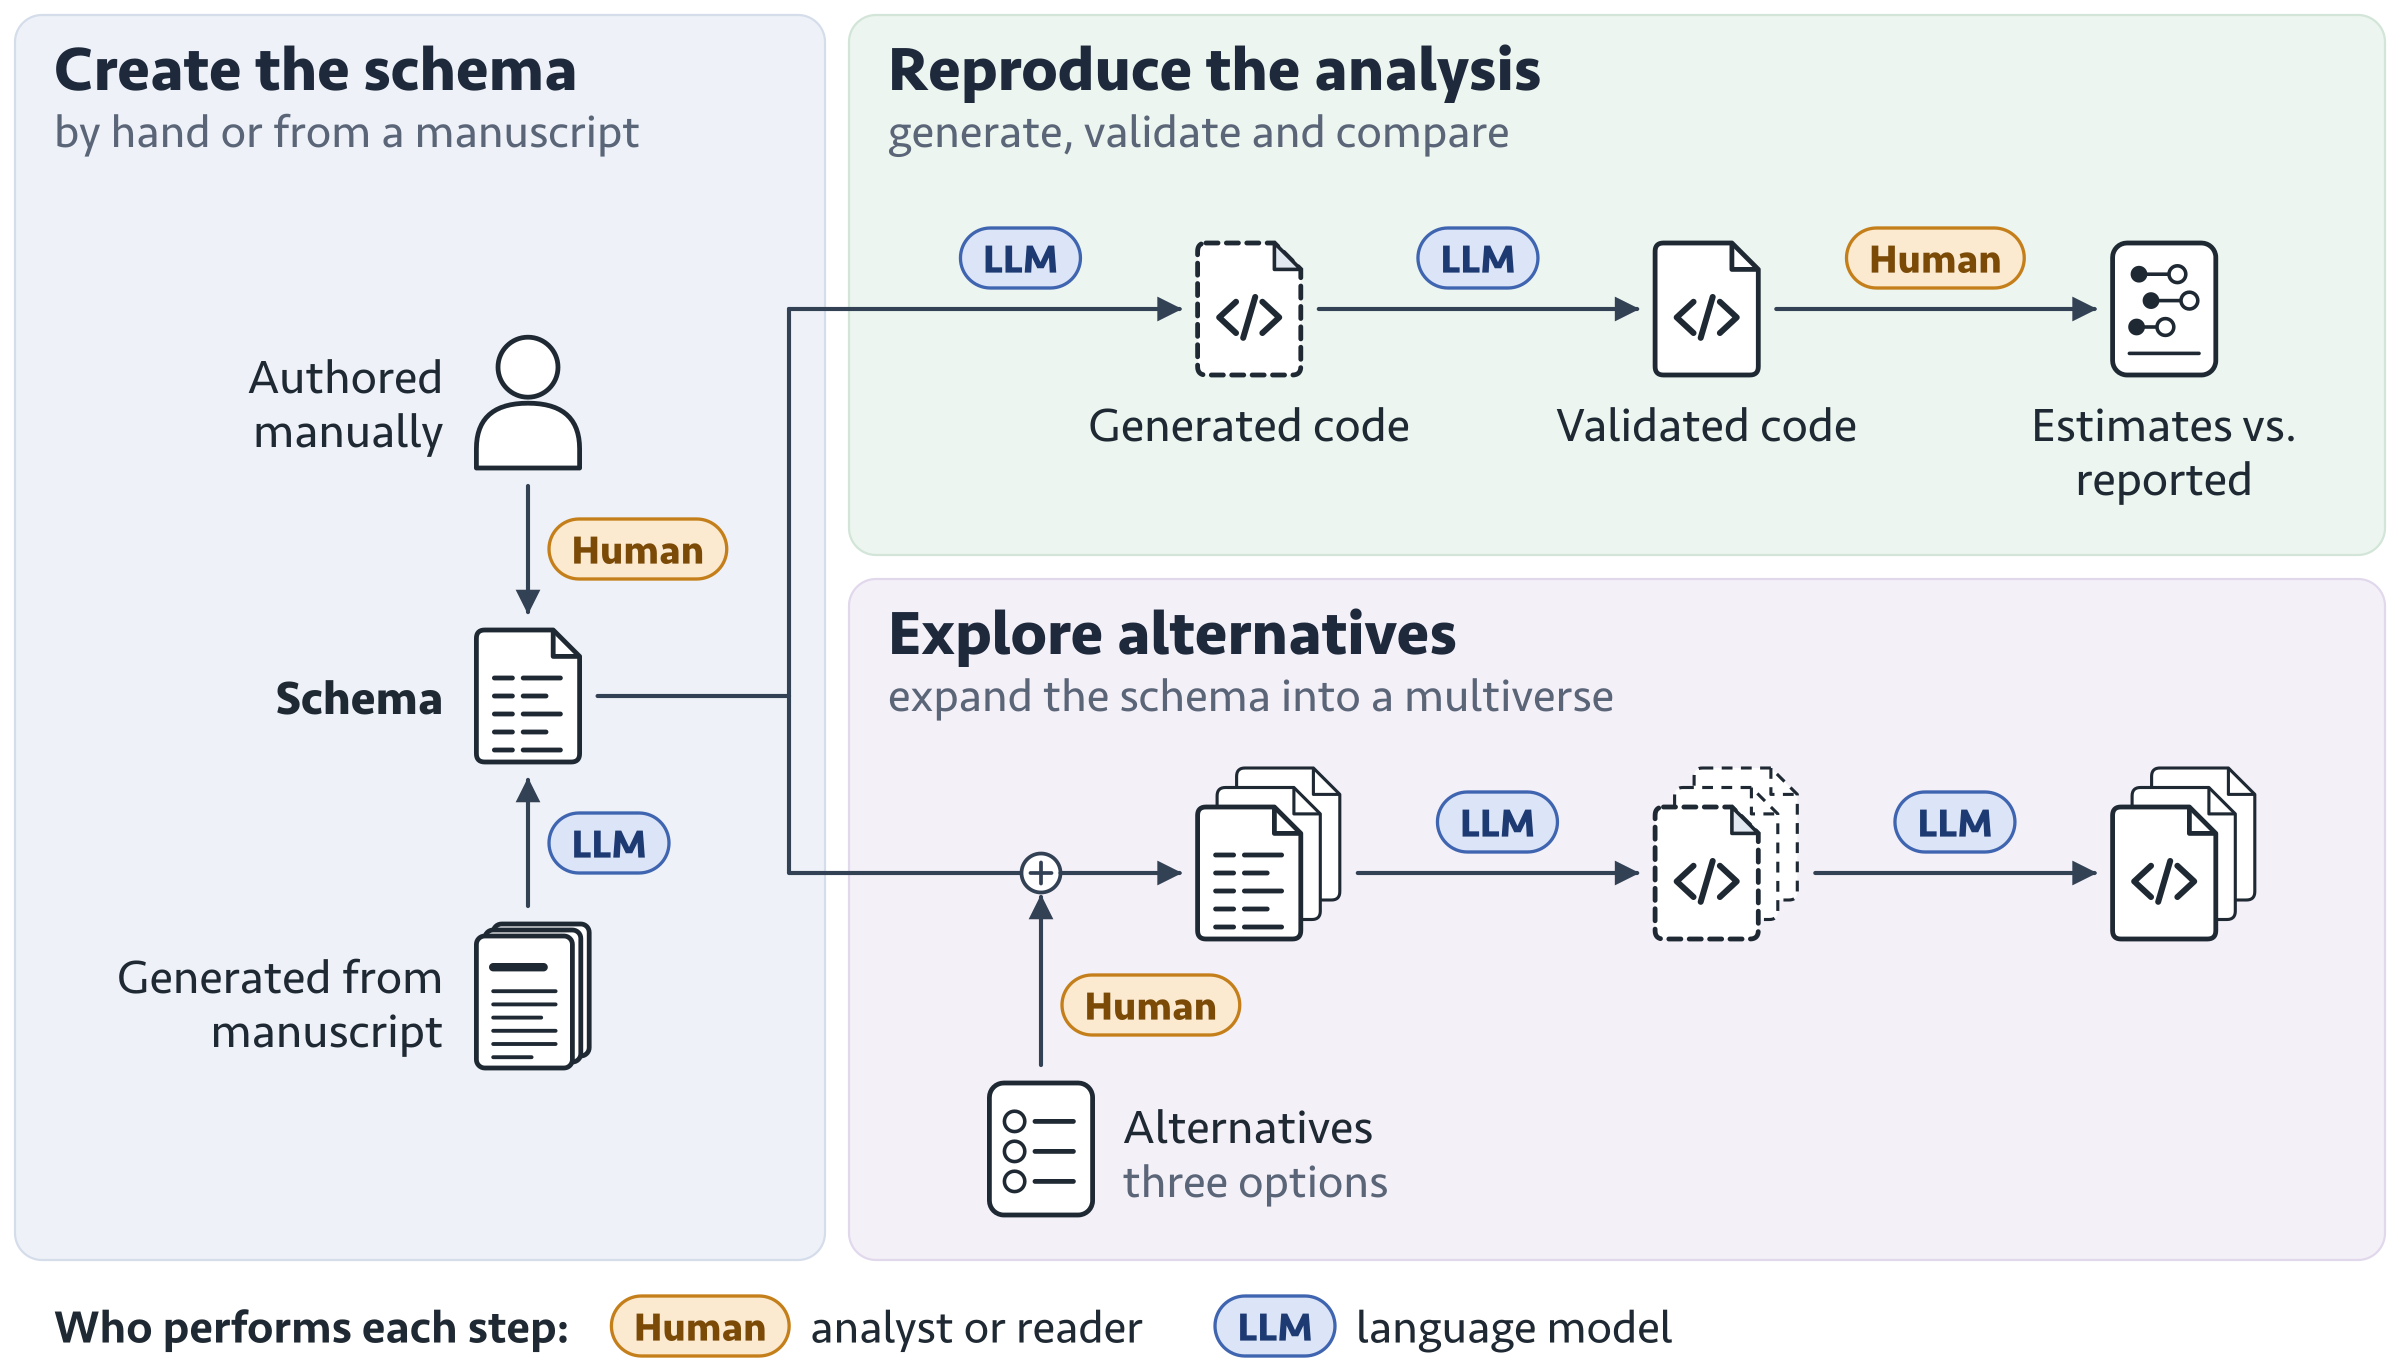
Building on a published analysis is often harder than it should be: the decisions behind a result are scattered across the manuscript, supplement, and code, and questions such as how the result would change under a different decision can be difficult to explore. With Roger Peng, I proposed a schema that records each decision and its rationale in plain language, from which LLMs can generate the analysis code. Because each decision is recorded as a separate step, alternative choices can be specified and turned into code, so that the alternatives can be compared directly (Figure 2). The schema keeps human judgment at the center of the analysis and leaves LLMs only the mechanical translation into code. We demonstrate it on a published regression analysis and on the many-analysts football study, where it also serves as a reproducibility check. Under review at the Annals of Applied Statistics.
Related work: